1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
|
@dataclass
class ModelArgs:
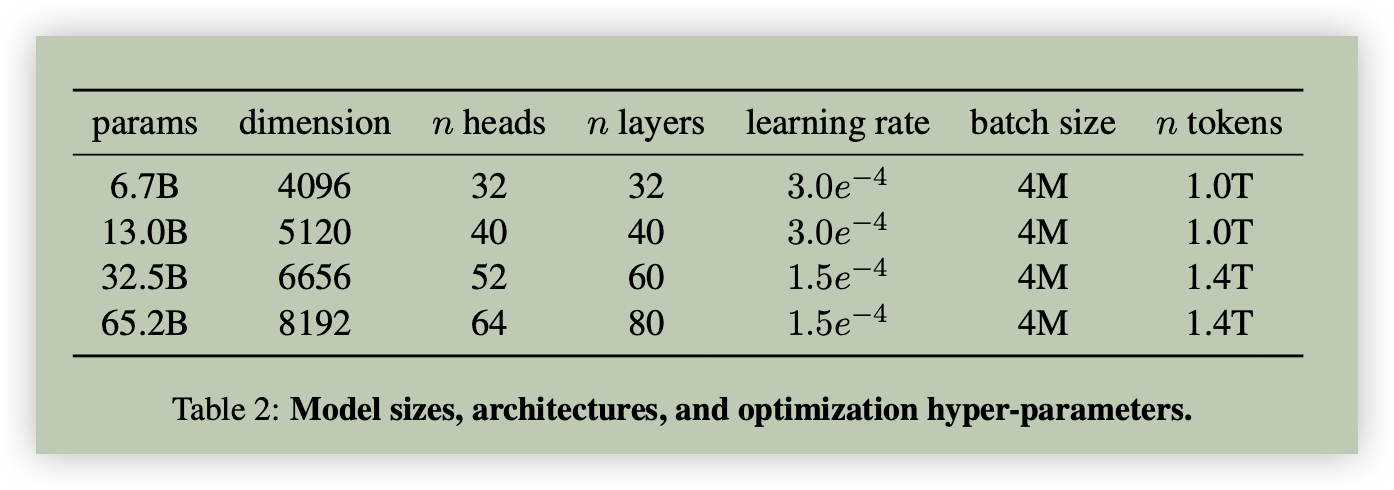
dim: int = 4096
n_layers: int = 32
n_heads: int = 32
n_kv_heads: Optional[int] = None
vocab_size: int = -1
multiple_of: int = 256
ffn_dim_multiplier: Optional[float] = None
norm_eps: float = 1e-5
max_batch_size: int = 32
max_seq_len: int = 2048
class RMSNorm(nn.Module):
"""
相比 LayerNorm,去掉 mean-centering 和 bias,只保留缩放。
RMSNorm(x) = x / sqrt(mean(x^2) + eps) * weight
"""
def __init__(self, dim: int, eps: float = 1e-6):
super().__init__()
self.eps = eps
self.weight = nn.Parameter(torch.ones(dim))
def _norm(self, x):
return x * torch.rsqrt(x.pow(2).mean(-1, keepdim=True) + self.eps)
def forward(self, x):
return self._norm(x.float()).type_as(x) * self.weight
def precompute_freqs_cis(dim: int, end: int, theta: float = 10000.0):
"""
预计算 RoPE 的复数频率 e^(i * t * theta_k)。
dim: head_dim
end: 最大位置数
返回: [end, dim//2] 的 complex64 张量
"""
freqs = 1.0 / (theta ** (torch.arange(0, dim, 2)[: (dim // 2)].float() / dim))
t = torch.arange(end, device=freqs.device)
freqs = torch.outer(t, freqs).float()
freqs_cis = torch.polar(torch.ones_like(freqs), freqs)
return freqs_cis
def reshape_for_broadcast(freqs_cis: torch.Tensor, x: torch.Tensor):
"""将 freqs_cis 形状调整为可与 x 广播。"""
ndim = x.ndim
assert 0 <= 1 < ndim
assert freqs_cis.shape == (x.shape[1], x.shape[-1])
shape = [d if i == 1 or i == ndim - 1 else 1 for i, d in enumerate(x.shape)]
return freqs_cis.view(*shape)
def apply_rotary_emb(xq, xk, freqs_cis):
"""
对 query 和 key 应用旋转位置编码。
xq, xk: [B, T, n_heads, head_dim]
freqs_cis: [T, head_dim//2] complex
做法: 把 head_dim 视为复数对 (2i, 2i+1),乘以 e^(i*angle) 实现旋转。
"""
xq_ = torch.view_as_complex(xq.float().reshape(*xq.shape[:-1], -1, 2))
xk_ = torch.view_as_complex(xk.float().reshape(*xk.shape[:-1], -1, 2))
freqs_cis = reshape_for_broadcast(freqs_cis, xq_)
xq_out = torch.view_as_real(xq_ * freqs_cis).flatten(3)
xk_out = torch.view_as_real(xk_ * freqs_cis).flatten(3)
return xq_out.type_as(xq), xk_out.type_as(xk)
def repeat_kv(x: torch.Tensor, n_rep: int) -> torch.Tensor:
"""
当 n_kv_heads < n_heads 时,把 KV heads 复制 n_rep 次以匹配 Q heads。
x: [B, T, n_kv_heads, head_dim] -> [B, T, n_kv_heads * n_rep, head_dim]
"""
bs, slen, n_kv_heads, head_dim = x.shape
if n_rep == 1:
return x
return (
x[:, :, :, None, :]
.expand(bs, slen, n_kv_heads, n_rep, head_dim)
.reshape(bs, slen, n_kv_heads * n_rep, head_dim)
)
class Attention(nn.Module):
def __init__(self, args: ModelArgs):
super().__init__()
self.n_kv_heads = args.n_heads if args.n_kv_heads is None else args.n_kv_heads
self.n_heads = args.n_heads
self.n_rep = self.n_heads // self.n_kv_heads
self.head_dim = args.dim // args.n_heads
self.wq = nn.Linear(args.dim, args.n_heads * self.head_dim, bias=False)
self.wk = nn.Linear(args.dim, self.n_kv_heads * self.head_dim, bias=False)
self.wv = nn.Linear(args.dim, self.n_kv_heads * self.head_dim, bias=False)
self.wo = nn.Linear(args.n_heads * self.head_dim, args.dim, bias=False)
self.cache_k = torch.zeros(
(args.max_batch_size, args.max_seq_len, self.n_kv_heads, self.head_dim)
)
self.cache_v = torch.zeros(
(args.max_batch_size, args.max_seq_len, self.n_kv_heads, self.head_dim)
)
def forward(self, x, start_pos, freqs_cis, mask):
bsz, seqlen, _ = x.shape
xq, xk, xv = self.wq(x), self.wk(x), self.wv(x)
xq = xq.view(bsz, seqlen, self.n_heads, self.head_dim)
xk = xk.view(bsz, seqlen, self.n_kv_heads, self.head_dim)
xv = xv.view(bsz, seqlen, self.n_kv_heads, self.head_dim)
xq, xk = apply_rotary_emb(xq, xk, freqs_cis=freqs_cis)
self.cache_k = self.cache_k.to(xq)
self.cache_v = self.cache_v.to(xq)
self.cache_k[:bsz, start_pos:start_pos + seqlen] = xk
self.cache_v[:bsz, start_pos:start_pos + seqlen] = xv
keys = self.cache_k[:bsz, :start_pos + seqlen]
values = self.cache_v[:bsz, :start_pos + seqlen]
keys = repeat_kv(keys, self.n_rep)
values = repeat_kv(values, self.n_rep)
xq = xq.transpose(1, 2)
keys = keys.transpose(1, 2)
values = values.transpose(1, 2)
scores = torch.matmul(xq, keys.transpose(2, 3)) / math.sqrt(self.head_dim)
if mask is not None:
scores = scores + mask
scores = F.softmax(scores.float(), dim=-1).type_as(xq)
output = torch.matmul(scores, values)
output = output.transpose(1, 2).contiguous().view(bsz, seqlen, -1)
return self.wo(output)
class FeedForward(nn.Module):
"""
SwiGLU: FFN(x) = W2( SiLU(W1 x) * W3 x )
hidden_dim 通常取 4*dim 的 2/3,且向上取整到 multiple_of 的倍数。
"""
def __init__(self, dim, hidden_dim, multiple_of, ffn_dim_multiplier=None):
super().__init__()
hidden_dim = int(2 * hidden_dim / 3)
if ffn_dim_multiplier is not None:
hidden_dim = int(ffn_dim_multiplier * hidden_dim)
hidden_dim = multiple_of * ((hidden_dim + multiple_of - 1) // multiple_of)
self.w1 = nn.Linear(dim, hidden_dim, bias=False)
self.w2 = nn.Linear(hidden_dim, dim, bias=False)
self.w3 = nn.Linear(dim, hidden_dim, bias=False)
def forward(self, x):
return self.w2(F.silu(self.w1(x)) * self.w3(x))
class TransformerBlock(nn.Module):
"""
Pre-Norm 结构:
h = x + Attention(RMSNorm(x))
out = h + FFN(RMSNorm(h))
"""
def __init__(self, layer_id, args):
super().__init__()
self.n_heads = args.n_heads
self.dim = args.dim
self.head_dim = args.dim // args.n_heads
self.attention = Attention(args)
self.feed_forward = FeedForward(
dim=args.dim,
hidden_dim=4 * args.dim,
multiple_of=args.multiple_of,
ffn_dim_multiplier=args.ffn_dim_multiplier,
)
self.layer_id = layer_id
self.attention_norm = RMSNorm(args.dim, eps=args.norm_eps)
self.ffn_norm = RMSNorm(args.dim, eps=args.norm_eps)
def forward(self, x, start_pos, freqs_cis, mask):
h = x + self.attention(self.attention_norm(x), start_pos, freqs_cis, mask)
out = h + self.feed_forward(self.ffn_norm(h))
return out
class Transformer(nn.Module):
def __init__(self, params: ModelArgs):
super().__init__()
self.params = params
self.vocab_size = params.vocab_size
self.n_layers = params.n_layers
self.tok_embeddings = nn.Embedding(params.vocab_size, params.dim)
self.layers = nn.ModuleList()
for layer_id in range(params.n_layers):
self.layers.append(TransformerBlock(layer_id, params))
self.norm = RMSNorm(params.dim, eps=params.norm_eps)
self.output = nn.Linear(params.dim, params.vocab_size, bias=False)
self.freqs_cis = precompute_freqs_cis(
self.params.dim // self.params.n_heads,
self.params.max_seq_len * 2,
)
@torch.inference_mode()
def forward(self, tokens, start_pos):
"""
tokens: [B, T]
start_pos: 当前 token 在序列中的起始位置(用于 KV Cache 和 RoPE)
"""
_bsz, seqlen = tokens.shape
h = self.tok_embeddings(tokens)
self.freqs_cis = self.freqs_cis.to(h.device)
freqs_cis = self.freqs_cis[start_pos:start_pos + seqlen]
mask = None
if seqlen > 1:
mask = torch.full((seqlen, seqlen), float("-inf"), device=tokens.device)
mask = torch.triu(mask, diagonal=1)
mask = torch.hstack([
torch.zeros((seqlen, start_pos), device=tokens.device),
mask
]).type_as(h)
for layer in self.layers:
h = layer(h, start_pos, freqs_cis, mask)
h = self.norm(h)
output = self.output(h).float()
return output
|