PMPP Chapter 01: Introduction
CPU vs. GPU
2003 年摩尔定律失效后,单核心 CPU 的频率/性能增长有限,新一代 CPU 的单核性能往往提升很小。面对这一问题 ,半导体产业产生了两条解决路径:
- 多核(multicore)CPU
- 多线程(multi-thread)GPU
在浮点运算性能(FLOPs)上,GPU 已经远远超过 CPU。这是因为二者设计哲学的区别:
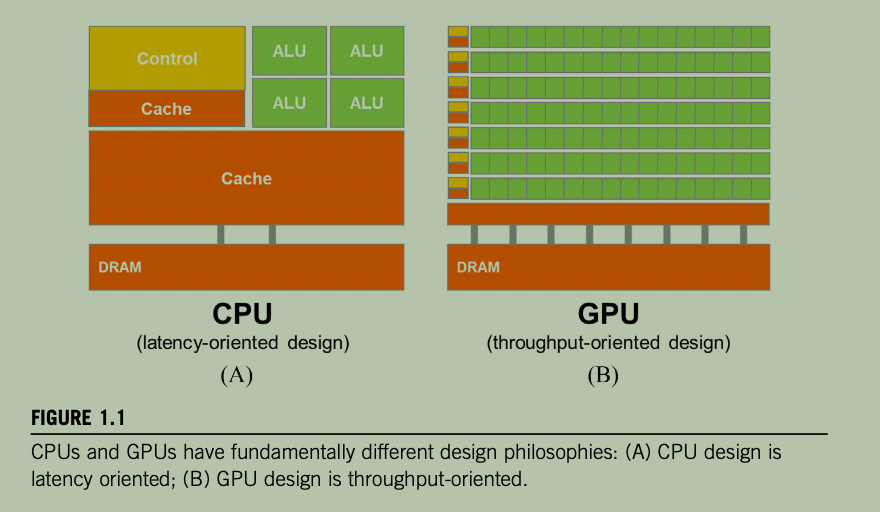
- CPU 设计目的是优化串行执行的代码性能
- Main Design Purpose: low-latency
- 大量芯片面积/晶体管用来实现复杂的 cache 管理
- 复杂的分支预测与控制单元
- GPU
- Main Design Purpose: high-throughput
- The relaxed memory model allows higher memory bandwidth than CPU(10+ times)
阿姆达尔定律 (Amdahl’s Law)
核心思想:系统整体加速比受限于不可并行(串行)部分。
公式: \[ \text{speedup} = \frac{1}{(1-p) + \frac{p}{S}} \]
- p: 可并行部分比例
- 1-p: 不可并行部分比例
- S: 可并行部分的加速倍数
使用 N 个处理器时: \[ \text{speedup}(N) = \frac{1}{(1-p) + \frac{p}{N}} \]
理论上限: \[ \lim_{N \to \infty} \text{speedup}(N) = \frac{1}{1-p} \]
本书组织
- Part I covers fundamental concepts in parallel programming, data
parallelism, GPUs, and performance optimization. (Chapters 2-6)
- Chapter 2, Heterogeneous Data Parallel Computing
- Chapter 3, Multidimensional Grids and Data
- Chapter 4, Compute Architecture and Scheduling
- Chapter 5, Memory Architecture and Data Locality
- Chapter 6, Performance Considerations
- Part II covers primitive parallel patterns. (Chapters 7-12)
- Chapter 7, Convolution
- Chapter 8, Stencil
- Chapter 9, Parallel Histogram
- Chapter 10, Reduction and Minimizing Divergence
- Chapter 11, Prefix Sum (Scan)
- Chapter 12, Merge
- Part III covers more advanced parallel patterns and applications.
(Chapters 13-19)
- Chapter 13, Sorting
- Chapter 14, Sparse Matrix Computation
- Chapter 15, Graph Traversal
- Chapter 16, Deep Learning
- Chapter 17, Iterative Magnetic Resonance Imaging Reconstruction
- Chapter 18, Electrostatic Potential Map
- Chapter 19, Parallel Programming and Computational Thinking
- Part IV, introduces advanced practices to complete the knowledge of
readers who would like to become expert GPU programmers. (Chapters
20-22)
- Chapter 20, Programming a Heterogeneous Computing Cluster
- Chapter 21, CUDA Dynamic Parallelism
- Chapter 22, Advanced Practices and Future Evolution
- Chapter 23, Conclusion and Outlook
PMPP Chapter 01: Introduction
https://arcsin2.cloud/posts/2026/09/1418183045/