LLM Systems 03: GPU Programming-2
This article is the learning note of CMU 11868 LLM Systems course Lecture 3. For more details, please refer to the original slides.
0. Recap
- GPU is composed of
- streaming processing units (SMs)
- each with four partitions of 32 cores
- shared L1 cache
- memory
- L2 cache: share with all SMs
- streaming processing units (SMs)
- Threads organized in
- grid of thread blocks
- each block is divided into warps running in parallel on one SM.
1. Basic GPU CUDA operations
1.1 memory management
Typical CUDA programming steps:
- CPU allocates GPU memory:
cudaMalloc - CPU copies data to GPU memory (host to device):
cudaMemcpy - CPU launches GPU kernels
- CPU copies results from GPU (device to host):
cudaMemcpy - Freeing GPU memory:
cudaFree
GPU memory hierarchy:
- Each thread has private registers (fastest to access)
- Each thread block has shared memory
- Visible to all threads in a block
__shared__
- All threads can access global gpu memory
- Persistent across kernel launches in the same app
TMA(Tensor Memory Accelerator) in H100:
void cuda::memcpy_async(void* destination, void const* source, Shape size, cuda::barrier<Scope, CompletionFunction>& barrier);- call
barrier.wait()to wait TMA copy completes.
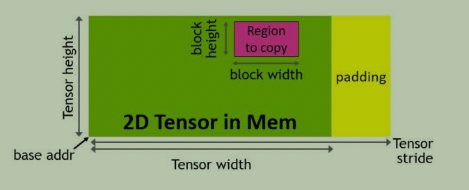
- 2D Tensor layout :
base addr: start of tensor in memory.Tensor width / height: dimensions of the tensor.Tensor stride: bytes between consecutive rows (includes padding).block width / height: the sub-region (pink) to copy.padding: extra memory at row ends; TMA handles stride and skips padding automatically.
1.2 defining functions to be executed on GPU
Declaration of Host/Device function
| keyword | call on | execute on |
|---|---|---|
__global__ |
host (cpu) | device (gpu) |
__device__ |
device (gpu) | device (gpu) |
__host__ |
host | host |
Define kernel function:
1 | |
1.3 launch kernel
Calling Kernel at Runtime
- Host program specifies grid-block-threads configurations for kernel
at run time
DgandDbare eitherdim3orint
1 | |
Dg: size of grid (num. of blocks)Dg.x * Dg.y * Dg.zis num. of blocks
Db: size of blockDb.x * Db.y * Db.zis num. of threads per block, <=1024)
Device Runtime Variables
- Host launches kernels on a gpu device
- Each kernel thread needs to know which thread it is running
- Compiler generates build-in variables, with x, y, z fields
| Name | Type | Explanation |
|---|---|---|
gridDim |
dim3 |
dimensions of grid |
blockIdx |
uint3 |
index of block within grid |
blockDim |
dim3 |
dimensions of block |
threadIdx |
uint3 |
index of thread within block |
Calling CUDA Kernel from CPU
1 | |
2. Matrix/Tensor Computation on GPU
Matrix Add
1 | |
3-D Grids & Blocks Demo
1 | |
3. Summary
- Basic GPU CUDA operations
- memory allocation
- data movement
- creating threads and running on SMs
- specifying number of threads and number of blocks in a grid
- referring to data in GPU memory within a thread
- using building index variables to refer to the data
LLM Systems 03: GPU Programming-2
https://arcsin2.cloud/posts/2026/09/667991994/